
What happened
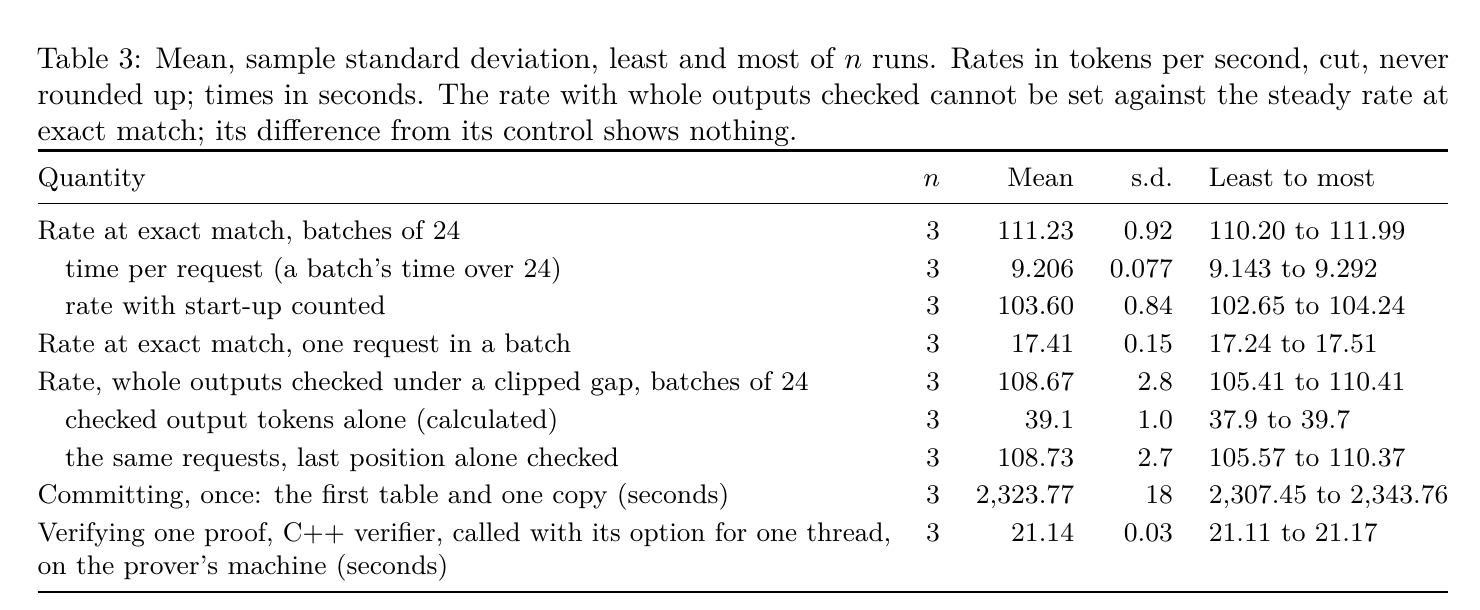
In the team’s test with a four-bit integer version of Llama 4 Maverick, one H100 processed about 111 input tokens per second for proofs in batches of 24. With one request per batch, the rate fell to about 17. A proof for a 1,024-token request was about 19 MB.
Why it matters
These are proving rates, not chatbot output speeds. The authors estimate that proving cost 70–95 times as much GPU time as ordinary inference in their comparison. The proof checks a specified computation; it cannot establish that an answer is true or safe.
What to watch
Independent reproductions and measurements at low batch sizes will matter for services where users cannot wait for many other requests to arrive.
Sources & verification
Source links are not a count of independent confirmations.
01Report a correction
Help us get it right
Include the disputed statement and, if possible, a supporting source URL. Please do not send personal or sensitive information.


