What happened
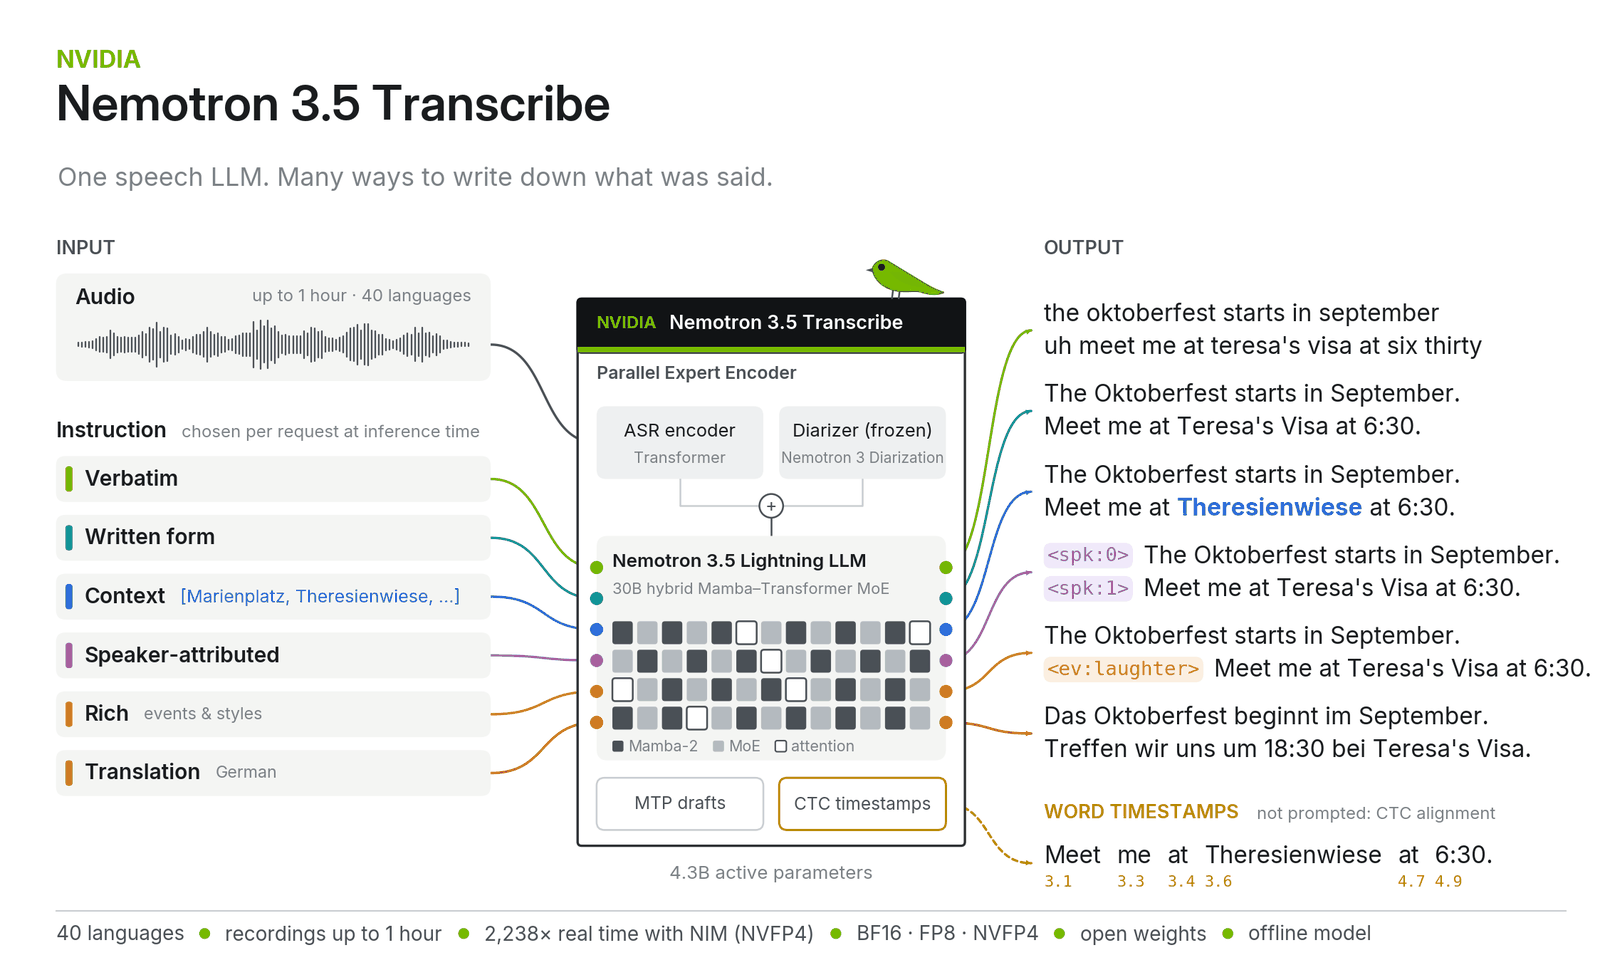
Documented tasks include verbatim and cleaned-up transcription, contextual vocabulary, speaker-attributed text, translation, language identification and audio question answering. Optional word timestamps help users navigate recordings. The model card lists BF16, FP8 and NVFP4 releases under OpenMDW-1.1.
The technical report explains that a readable meeting record, a verbatim interview and a transcript containing specialized names require different treatment of the same speech. One speech-augmented model responds to these instructions rather than fixing every transcription convention in advance.
This is an offline recording-processing model, not a complete live voice agent. Speaker labels distinguish voices within a recording; they do not establish real-world identities.
Why it matters
For contact centres, publishers and internal knowledge systems, the opportunity is a more adaptable processing stage after audio has been captured. A live voice agent additionally requires streaming behavior, dialogue handling and reliable turn-taking; those capabilities should not be inferred from a transcription release.
What to watch
Test representative accents, background noise, overlapping speech and specialist vocabulary. Compare correction effort and processing cost alongside word-error scores, and retain human review where an error could materially change the meaning.
Sources & verification
Source links are not a count of independent confirmations.
01Report a correction
Help us get it right
Include the disputed statement and, if possible, a supporting source URL. Please do not send personal or sensitive information.