What happened
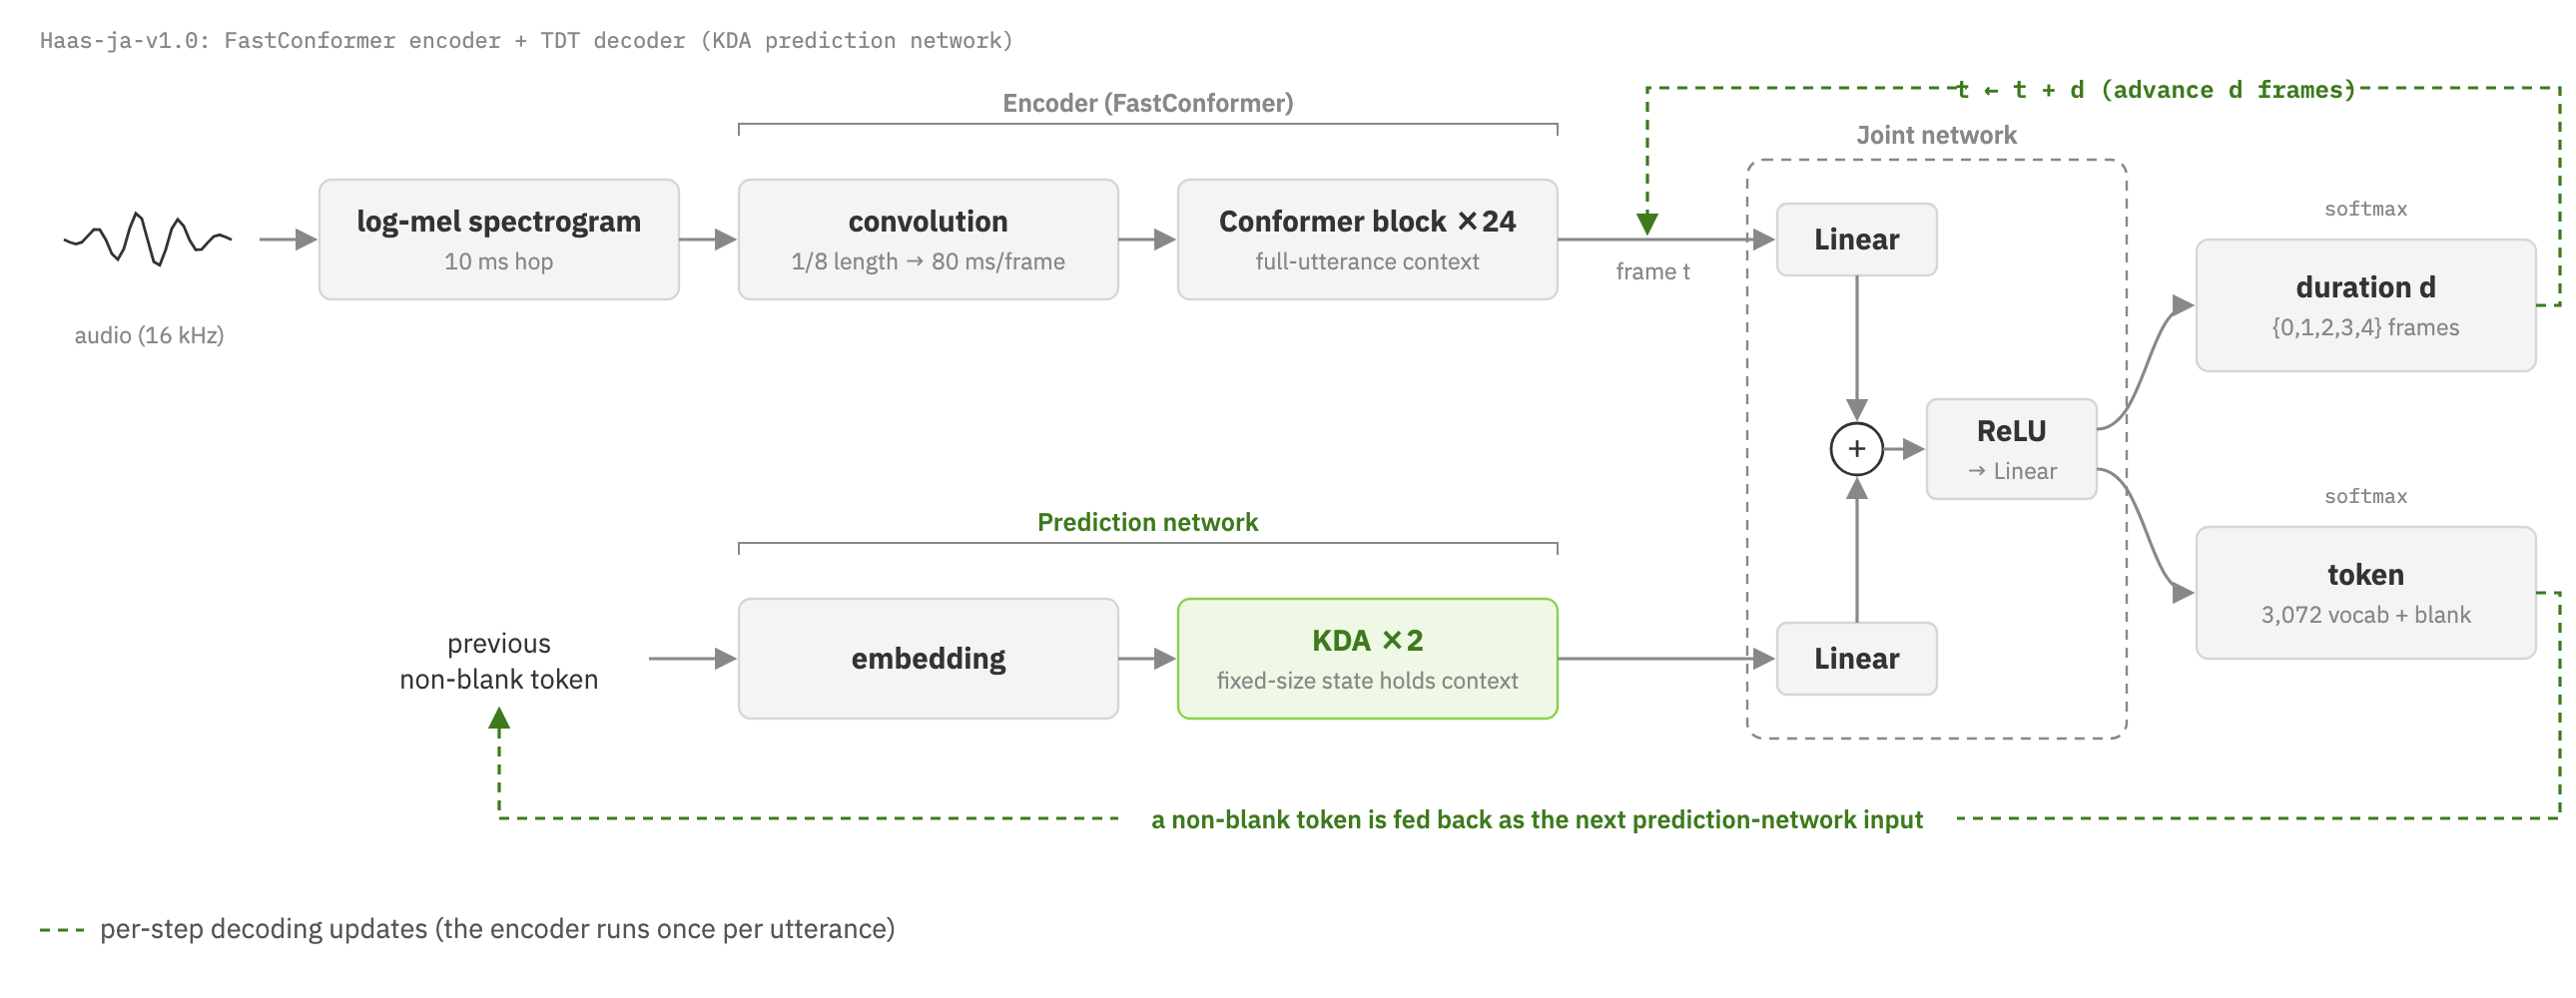
The model uses a FastConformer encoder and a TDT decoder with Kimi Delta Attention. The official repository links downloadable weights and Apache-2.0 inference code; its tested setup requires Linux, an NVIDIA GPU and Python 3.11 or newer.
The developer reports a 6.12% weighted strict character error rate across five Japanese datasets. This is a defined benchmark result, not proof of universal superiority.
Why it matters
Our analysis: local transcription can give teams more control over audio processing, but hardware costs and accuracy on their own recordings matter. Custom-vocabulary boosting can also insert an incorrect listed word.
What to watch
Watch independent tests on noisy calls, specialist vocabulary and end-to-end deployment costs.
Sources & verification
Source links are not a count of independent confirmations.
01Report a correction
Help us get it right
Include the disputed statement and, if possible, a supporting source URL. Please do not send personal or sensitive information.